AI Services Advanced Guide: Asynchrony, Batching, Multi-Key
Step 1: Imports and Keys
from synapse.ml.core.platform import find_secret

service_key = find_secret(
    secret_name="ai-services-api-key", keyvault="mmlspark-build-keys"
)
service_loc = "eastus"
Step 2: Basic Usage
| Image 1 | Image 2 | Image 3 |
|---|---|---|
!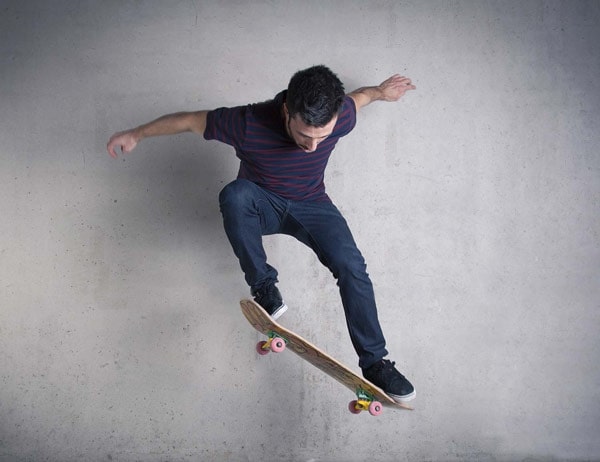 | 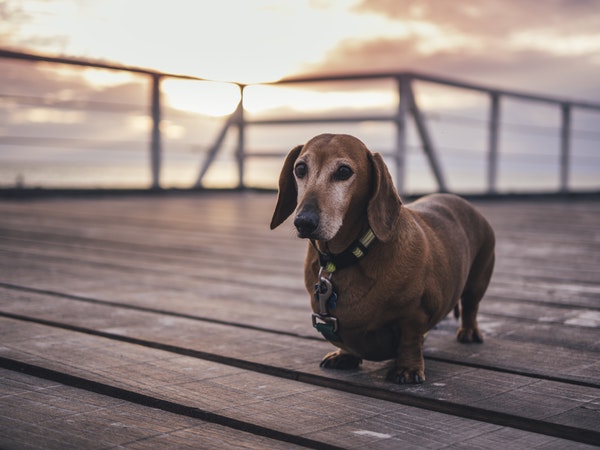 |  |
from synapse.ml.services.vision import AnalyzeImage

# Create a dataframe with the image URLs
base_url = "https://raw.githubusercontent.com/Azure-Samples/cognitive-services-sample-data-files/master/ComputerVision/Images/"
image_df = spark.createDataFrame(
    [(base_url + "objects.jpg",), (base_url + "dog.jpg",), (base_url + "house.jpg",)],
    ["image"],
)

# Run the Computer Vision service. Analyze Image extracts infortmation from/about the images.
analyzer = (
    AnalyzeImage()
    .setLocation(service_loc)
    .setSubscriptionKey(service_key)
    .setVisualFeatures(
        ["Categories", "Color", "Description", "Faces", "Objects", "Tags"]
    )
    .setOutputCol("analysis_results")
    .setImageUrlCol("image")
    .setErrorCol("error")
)

image_results = analyzer.transform(image_df).cache()
First we'll look at the full response objects:
display(image_results)
We can select out just what we need:
display(image_results.select("analysis_results.description.captions.text"))
What's going on under the hood

When we call the AI service transformer, we start cognitive service clients on each of your spark workers. These clients send requests to the cloud, and turn the JSON responses into Spark Struct Types so that you can access any field that the service returns.
Step 3: Asynchronous Usage

Apache Spark ordinarily parallelizes a computation to all of its worker threads. When working with services, however, this parallelism doesn't fully maximize throughput because workers sit idle as requests are processed on the server. The concurrency parameter makes sure that each worker can stay busy as they wait for requests to complete.
display(analyzer.setConcurrency(3).transform(image_df))
Faster without extra hardware:

Step 4: Batching
from synapse.ml.services.language import AnalyzeText

# Create a dataframe
text_df = spark.createDataFrame(
    [
        ("I am so happy today, its sunny!",),
        ("I am frustrated by this rush hour traffic",),
        ("The AI services on spark is pretty lit",),
    ],
    ["text"],
)

sentiment = (
    AnalyzeText()
    .setKind("SentimentAnalysis")
    .setTextCol("text")
    .setLocation(service_loc)
    .setSubscriptionKey(service_key)
    .setOutputCol("sentiment")
    .setErrorCol("error")
    .setBatchSize(10)
)

# Show the results of your text query
display(sentiment.transform(text_df).select("text", "sentiment.documents.sentiment"))
Step 5: Multi-Key
Note: An automatically batched transformer sends one HTTP request per batch. Each credential column uses its first non-blank value, with the usual authentication precedence deciding which credential authenticates the entire request. Header-map columns use their first non-empty map after null entries are removed; maps from later rows are not merged. Batching does not group rows by credential, and the original per-row columns are preserved in the output. Use a batch size of 1 when every row must select its own credential.
from pyspark.sql.functions import udf
import random

service_key_2 = find_secret(
    secret_name="ai-services-api-key-2", keyvault="mmlspark-build-keys"
)
keys = [service_key, service_key_2]


@udf
def random_key():
    return keys[random.randint(0, len(keys) - 1)]


image_df2 = image_df.withColumn("key", random_key())

results = analyzer.setSubscriptionKeyCol("key").transform(image_df2)
display(results.select("key", "analysis_results.description.captions.text"))