Frontier
Frontier
Explore synthetic Viva Insights dashboards, or use prompts, Skills and schema guides to build and review your own analysis.
Frontier brings together dashboard examples, prompts, agent Skills and schema guides for Viva Insights. Explore a synthetic report in your browser, or use a coding agent such as GitHub Copilot or Claude Code to build an analysis from your exports. Review the inputs, calculations and limitations before sharing the output.
Note: Everything in this section is sample code and starter assets. It is not production software. Outputs require review, validation, and adaptation to your environment before use.
Quick start with a coding agent
Follow these steps to validate a Person Query, then choose a report to build. Use a coding agent and data-handling environment approved by your organisation. If you want to explore an example first, open the synthetic dashboard demos without installing anything.
1. Prepare a private working folder and your export
Create a folder outside this public sample repository. For example, run the following in PowerShell from an approved location for your analysis:
New-Item -ItemType Directory -Path viva-insights-workspace
Set-Location viva-insights-workspace
New-Item -ItemType Directory -Path data, output
In the Viva Insights Analyst portal, create and download a Person Query.
Save its CSV as data\person-query.csv, or use your own filename in the prompt
below. Keep the query’s population, date grouping, week start and metric settings
alongside the export. Start with the Person Query schema
to check the required columns. For several exports, also use the
query join guide.
No export yet? The sample-data examples
show how to load pq_data in R or load_pq_data() in Python. Tell the agent to
use that sample instead of a CSV and label every output as sample data.
2. Set up R or Python
Choose one language for general analysis. The reference dashboard templates require R and their additional rendering dependencies.
Python: install the package in an isolated environment
Install Python if needed, then run these commands in PowerShell from your working folder:
python -m venv .venv
.\.venv\Scripts\python.exe -m pip install vivainsights
.\.venv\Scripts\python.exe -c "from importlib.metadata import version; import vivainsights; print(version('vivainsights'))"
The last command should print the installed version without an import error.
Tell the agent to use .\.venv\Scripts\python.exe so it uses this environment.
For other operating systems, see the environment setup guide.
The Python function guide
lists supported analyses.
R: install the package and check it loads
Install R and, optionally, RStudio. Run this in the R console:
install.packages("vivainsights")
library(vivainsights)
packageVersion("vivainsights")
The last command should print the installed version without an error. The R function guide lists supported analyses. See Getting Started for import and plotting examples.
3. Install the analysis Skill and open your agent
For GitHub Copilot CLI, install GitHub CLI and Copilot CLI if needed. Run this in your working folder:
gh skill install microsoft/viva-insights-sample-code frontier-analytics/skills/viva-insights-analysis --agent github-copilot --scope user
copilot skill list
copilot
Check that viva-insights-analysis appears in the Skill list, then sign in if
prompted when opening Copilot. The install command copies the whole Skill,
including its references and examples, into your personal Skills directory.
Review the files before use. The Skill does not install R, Python or packages.
For Claude Code, use the same install command with --agent claude-code,
then open Claude Code in your working folder. Its
setup guide
covers installation and launch. If gh skill is unavailable, update GitHub CLI
or follow the whole-folder installation instructions.
Review existing customised Skills before replacing them.
If your agent does not support Skills, use the context file and a prompt card instead.
4. Run a validation pass before building
Paste this into the agent. Change the filename if needed. For R, replace the Python sentence with “Use R and the vivainsights package.”
Use the installed viva-insights-analysis Skill and its shared analysis policy.
Confirm that the Skill is available before starting.
Use Python and the vivainsights package through .\.venv\Scripts\python.exe.
My Person Query CSV is data\person-query.csv, relative to this working folder.
Save generated files under output and leave the source export unchanged.

Inspect the actual headers, installed package version, row count, distinct
people, date range, duplicate person-period keys and missingness. Ask me for
any missing query settings, including grouping, week start and metric windows.
Do not infer cadence from gaps between dates.

Use existing package functions after checking their installed signatures.
Keep individual records out of the report. Apply the stricter organisational
minimum or 10 distinct people to every published group and its complement.
Summarise coverage and data-quality issues, separating executed checks from
checks you could not run. Save the validation summary and reproducible code.

Propose a supported analysis of Copilot usage by available organisational
attributes. If suitable attributes are absent, propose overall results.
Stop for my review before building the report or making productivity claims.
Check the saved summary against your query settings. Resolve duplicate keys, coverage gaps and uncertain metric definitions before approving the analysis. The data-pitfalls reference explains common import problems. The shared analysis policy sets out privacy, licence and aggregation rules.
5. Choose the next prompt
Open a card below, copy its quick or detailed prompt and add your file location and preferred language. Use the same agent session so it retains the validation results. Check the card’s inputs and limitations before asking it to build.
| What you want to produce | Start here |
|---|---|
| A Copilot adoption dashboard from a Person Query | Dashboard Overview |
| A short leadership briefing | Executive Summary |
| AI adoption across Person, Consumption and Agent queries | AI Adoption Across Tools |
| Descriptive workload and connected-time signals | Employee Wellbeing and Workload Signals |
| External participation and collaboration hours | External Collaboration Patterns |
The AI adoption, wellbeing and external collaboration cards are guided prompts without completed end-to-end data trials. Their outputs require validation. For the R reference templates, use the Consumption journey or Developer Experience journey. Each links its rendering requirements and supported real-data scope. Repeated dashboard work can use the paired dashboard Skill installation. Business Leaders has a separate rendering guide and no verified real-export adapter.
Before sharing, rerun the saved code, reconcile headline counts and denominators, check privacy suppression in charts and embedded data, and open any self-contained HTML report offline. Keep the source and validation log with the output.
Which asset should I use?
Frontier offers three ways to bring this work into a coding agent. Pick a card to jump straight to what you need, or use the comparison below.
Full comparison
| Mechanism | What it is | Status | Use it when |
|---|---|---|---|
| Prompt Library | Structured text you copy and paste into any coding agent for a single analysis task. | Available | You want a one-off analysis without installing a Skill. |
| Agent Skills | A packaged capability that a compatible coding agent loads automatically, so it applies the right conventions without you pasting anything. | Available | Your coding agent supports the Skill format (for example GitHub Copilot CLI or Claude Code) and you want ongoing, repeated Viva Insights work to follow consistent conventions. |
| vivainsights-context.md | A single context file you paste once at the start of a session. | Available | Your agent does not support Skills, but you still want to avoid repeating setup instructions in every prompt. |
Who is this for?
- People analytics leads building dashboards and reports from Viva Insights exports
- HR analysts who need repeatable, transparent analysis workflows
- Analytics consultants delivering Copilot adoption or workplace analytics engagements
- Technically capable users comfortable with R or Python and willing to work with a coding agent
You do not need to be a software engineer. If you can export a CSV from Viva Insights and paste a prompt into a coding agent, you can use these assets.
What’s inside
Explore the dashboard demos
Open any of these three reports in your browser without installing anything. They use synthetic data and include R Markdown source and rendering requirements. Select Start using for the links and capability limits.
Business Leaders AI Usage brings together M365 Copilot, Cowork, Agent, Consumption and GitHub Copilot fixtures. Explore reach, usage and trends over four, eight or thirteen weeks by organisation, function and team. It is a synthetic reference dashboard, with no verified real-export adapter or dedicated prompt journey. Descriptive comparisons do not establish causal effects.
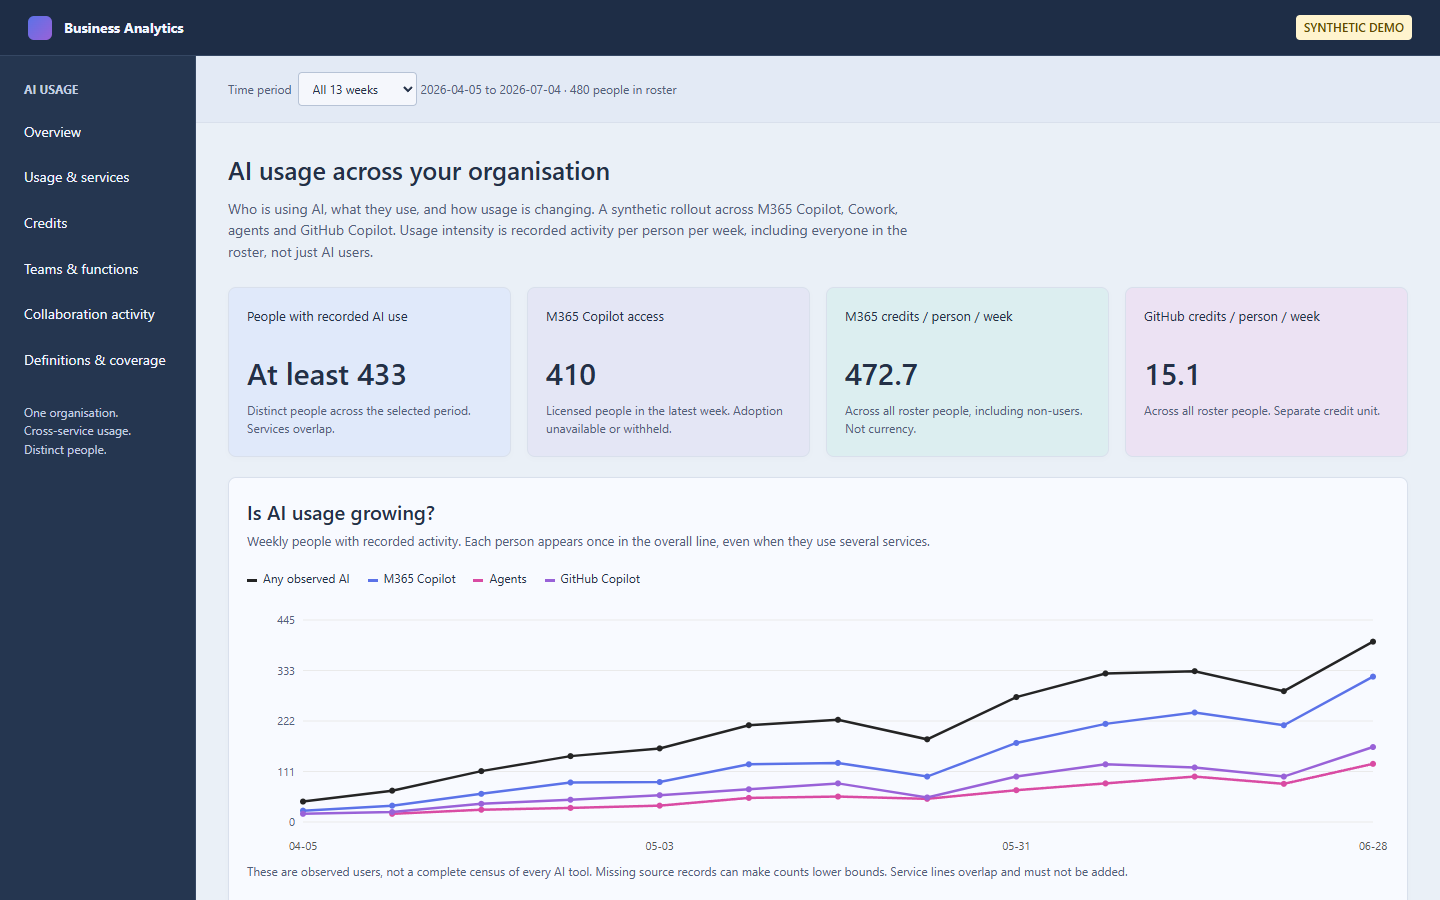
Synthetic data · R template
Business Leaders AI Usage
Who is using AI, how much, and how does usage vary over time and across groups?
Full guide for Business Leaders AI Usage Start using Business Leaders AI Usage
Synthetic data · R template
Copilot Consumption and Ways of Working
How is Copilot consumed, and how does consumption relate to collaboration?
Full guide for Copilot Consumption and Ways of Working Start using Copilot Consumption and Ways of Working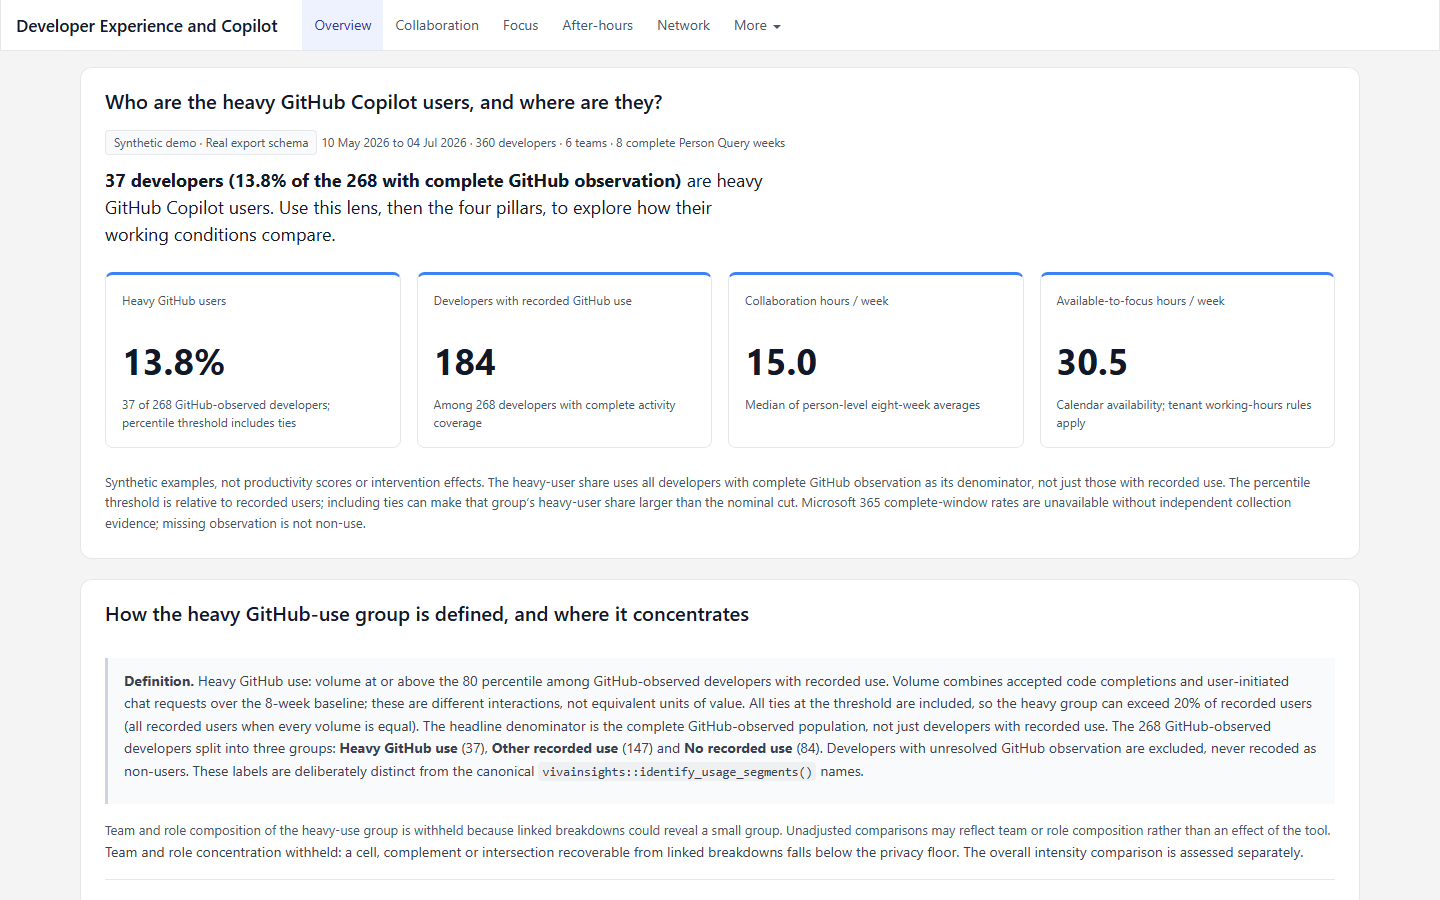
Synthetic data · R template
Developer Experience and Copilot
What do developer working conditions and joint Copilot use look like?
Full guide for Developer Experience and Copilot Start using Developer Experience and CopilotBusiness Leaders AI Usage
Synthetic data · R template
Explore four, eight or thirteen weeks by organisation, function and team. Reach counts distinct people across sources; recorded usage is per person per week across the full roster, including non-users.
View demo · Get source · Rendering and input requirements
Start using
- Open the synthetic demo in your browser. No installation is required.
- To render it locally, clone the whole repository so that the source, helpers and synthetic fixtures stay together. You will need Git, R and Pandoc (also supplied with RStudio).
git clone https://github.com/microsoft/viva-insights-sample-code.git
cd viva-insights-sample-code
R packages: dplyr, tidyr, jsonlite, knitr, rmarkdown. Install missing packages from your approved package source. For CRAN:
Rscript -e "install.packages(c('dplyr', 'tidyr', 'jsonlite', 'knitr', 'rmarkdown'), repos='https://cloud.r-project.org')"
Rscript -e "stopifnot(rmarkdown::pandoc_available())"
Run this from the repository root in a terminal:
New-Item -ItemType Directory -Force ..\copilot-dashboard-work\business-leaders
Rscript examples\utility-r\render-business-leaders-ai.R ..\copilot-dashboard-work\business-leaders\dashboard.html
Expected output: ..\copilot-dashboard-work\business-leaders\dashboard.html, outside the checkout so the tracked demo is not overwritten. It is a self-contained HTML file with four-, eight- and thirteen-week views, group comparisons and separate product credit rates.
Demo inputs: Person, M365 Copilot, Cowork, Agent, Consumption and GitHub Copilot fixtures.
Using real exports: Synthetic reference only. A real-data adaptation needs a separately implemented and verified mapping, coverage assessment and disclosure review.
Work with a coding agent
This report is not supported by the optional dashboard Skill runner. Ask your agent to use the dedicated renderer with this prompt:
Reproduce the synthetic Business Leaders AI Usage report from my local viva-insights-sample-code checkout at [path]. Read its rendering guide and use render-business-leaders-ai.R, not the dashboard Skill runner. Check dependencies first and ask before installing them. Save to a fresh output HTML path and report the command, validation and coverage limits.Capability and interpretation: This is a synthetic reference, not a verified real-export adapter. Coverage is limited to observed usage within the Person Query roster. M365 Copilot credits and GitHub AI credits remain separate; descriptive comparisons do not establish causation.
Before sharing: review coverage and your organisation's privacy requirements, including data embedded in the HTML. Keep customer exports outside this repository.
Full dashboard details and caveats · Query and setup requirements · Query setup and joins
Copilot Consumption and Ways of Working
Synthetic data · R template
Separate credit volume from cost per session, explore concentration and heavy-user patterns, and compare services, organisations and functions in a seven-page report.
View demo · Get source · Rendering and input requirements
Start using
- Open the synthetic demo in your browser. No installation is required.
- To render it locally, clone the whole repository so that the source, helpers and synthetic fixtures stay together. You will need Git, R and Pandoc (also supplied with RStudio).
git clone https://github.com/microsoft/viva-insights-sample-code.git
cd viva-insights-sample-code
R packages: jsonlite, rmarkdown, flexdashboard, dplyr, tidyr, ggplot2, scales, knitr, stringr, vivainsights, ggrepel. Install missing packages from your approved package source. For CRAN:
Rscript -e "install.packages(c('jsonlite', 'rmarkdown', 'flexdashboard', 'dplyr', 'tidyr', 'ggplot2', 'scales', 'knitr', 'stringr', 'vivainsights', 'ggrepel'), repos='https://cloud.r-project.org')"
Rscript -e "stopifnot(rmarkdown::pandoc_available())"
Run this from the repository root in a terminal:
Rscript frontier-analytics\starter-kits\copilot-query-dashboard\dashboard.R reproduce frontier-analytics\starter-kits\copilot-query-dashboard\configs\demo-consumption.jsonThe demo configuration selects an output folder outside the checkout. Choose a fresh folder if it already exists. The runner refuses to overwrite a previous run.
Expected output: A seven-page synthetic HTML report, provenance.json and an isolated working copy under the configured output_dir\reproduce folder outside the repository.
Demo inputs: Five fixture files across Person, Consumption and GitHub queries; GitHub breakdown files are not used.
Using real exports: M365 credits by period and service, with optional grouping when the metadata supports it. Inspect the activity and matching people metadata first, approve exact mappings and confirm spending-policy additivity when required.
Work with a coding agent
Install the dashboard and analysis Skills from the same checkout. Keep the checkout because the Skill runs its R code.
From the parent folder containing your checkout:
gh skill install ./viva-insights-sample-code viva-insights-analysis --from-local --agent github-copilot --scope user
gh skill install ./viva-insights-sample-code viva-insights-copilot-dashboards --from-local --agent github-copilot --scope user
Reload the Skills in your agent, then replace [path] in this starter prompt:
Use the Copilot query dashboards Skill to reproduce the synthetic Consumption demo. My checkout is at [path]. Check dependencies before rendering and ask before installing them. Use a fresh private output directory, preserve the reference files, and return the HTML location, configuration, provenance and validation summary. Explain which demo panels are excluded from the real M365 credits-only adapter.Capability and interpretation: The real-v1 runner supports only M365 credits from Consumption activity and matching people metadata, with explicit mapping approval. Sessions, Person Query associations and GitHub panels are not implemented by that adapter. Credit intensity does not measure value or quality.
Before sharing: review coverage and your organisation's privacy requirements, including data embedded in the HTML. Keep customer exports outside this repository.
Full dashboard details and caveats · Query and setup requirements · Query setup and joins
Developer Experience and Copilot
Synthetic data · R template
Compare collaboration, focus, after-hours activity and network breadth across three GitHub-intensity groups. Explore joint M365 and GitHub use while keeping observation and eligibility gaps visible.
View demo · Get source · Rendering and input requirements
Start using
- Open the synthetic demo in your browser. No installation is required.
- To render it locally, clone the whole repository so that the source, helpers and synthetic fixtures stay together. You will need Git, R and Pandoc (also supplied with RStudio).
git clone https://github.com/microsoft/viva-insights-sample-code.git
cd viva-insights-sample-code
R packages: jsonlite, rmarkdown, flexdashboard, dplyr, tidyr, ggplot2, scales, knitr, stringr, vivainsights. Install missing packages from your approved package source. For CRAN:
Rscript -e "install.packages(c('jsonlite', 'rmarkdown', 'flexdashboard', 'dplyr', 'tidyr', 'ggplot2', 'scales', 'knitr', 'stringr', 'vivainsights'), repos='https://cloud.r-project.org')"
Rscript -e "stopifnot(rmarkdown::pandoc_available())"
Run this from the repository root in a terminal:
Rscript frontier-analytics\starter-kits\copilot-query-dashboard\dashboard.R reproduce frontier-analytics\starter-kits\copilot-query-dashboard\configs\demo-github.jsonThe demo configuration selects an output folder outside the checkout. Choose a fresh folder if it already exists. The runner refuses to overwrite a previous run.
Expected output: A self-contained synthetic HTML report with Overview, Collaboration, Focus, After-hours, Network and additional breakdowns, plus provenance.json and isolated work files under output_dir\reproduce.
Demo inputs: Person, GitHub and Consumption fixtures, including GitHub feature, model and language breakdowns.
Using real exports: Readiness inspection only. The runner does not build this dashboard from real GitHub exports. Missing observation must not be relabelled as zero use or as lack of provisioning.
Work with a coding agent
Install the dashboard and analysis Skills from the same checkout. Keep the checkout because the Skill runs its R code.
From the parent folder containing your checkout:
gh skill install ./viva-insights-sample-code viva-insights-analysis --from-local --agent github-copilot --scope user
gh skill install ./viva-insights-sample-code viva-insights-copilot-dashboards --from-local --agent github-copilot --scope user
Reload the Skills in your agent, then replace [path] in this starter prompt:
Use the Copilot query dashboards Skill to reproduce the synthetic Developer Experience demo. My checkout is at [path]. Check dependencies and ask before installing them. Use a fresh private output directory and return the HTML location, configuration, provenance and validation summary. Keep the GitHub observation limits and privacy gates visible. If I later supply real exports, inspect readiness only because no verified real GitHub build adapter is supplied.Capability and interpretation: No verified real GitHub dashboard adapter is supplied. Synthetic breakdown allocations are not verified real-export semantics. Acceptance rate is not code quality, after-hours activity is not burnout, and calendar space does not establish coding time.
Before sharing: review coverage and your organisation's privacy requirements, including data embedded in the HTML. Keep customer exports outside this repository.
Full dashboard details and caveats · Query and setup requirements · Query setup and joins
Build or customise the query dashboards
These two guided journeys reproduce the existing Consumption and Developer Experience R demos. The agent inspects real inputs and asks you to approve supported analyses before building. Missing metrics and coverage remain explicit.
| Journey | Demo | Real-data support |
|---|---|---|
| Consumption Dashboard | Full synthetic reference | Documented credit consumption; token/task-type and Person Query panels excluded |
| Developer Experience Dashboard | Full synthetic reference | Input-readiness assessment only; real adapter not yet verified |
Browse the dashboard examples or install the optional dashboard skill for repeated work. Prompt-only use requires no skill installation.
| Section | Description |
|---|---|
| Schema Documentation | Data dictionaries for person query exports, Purview audit logs, join patterns, and common data pitfalls. |
Additional resources available on GitHub:
| Folder | Description |
|---|---|
| examples/ | Sample output specifications describing what a finished deliverable looks like. |
| templates/ | Templates for contributing new prompt cards, skills, and schema docs. |
Getting started
Prerequisites
Viewing the synthetic demos above needs only a browser. To run a prompt or render a report, check its specific requirements. The general analysis prompts use R or Python. The dashboard templates require R, Pandoc, R Markdown, flexdashboard and the packages listed in their rendering requirements.
For analysis of your own exports, prepare:
-
Exported Viva Insights data. Use the query types required by the selected workflow. A Person Query has rows keyed by
PersonIdandMetricDate(person-week or person-day granularity). HR attributes such as organisation, function, geography and level are included as columns. Cross-query dashboards may need several exports. - An R or Python environment. You need one of the following set up locally:
- R (4.1+) with vivainsights installed:
install.packages("vivainsights") - Python (3.9+) with vivainsights installed:
pip install vivainsights
- R (4.1+) with vivainsights installed:
- A coding agent. Any AI-assisted coding tool that can run R or Python:
- GitHub Copilot (in VS Code, JetBrains, or CLI)
- Claude Code
- Other coding agents with code execution capabilities
Don’t have a coding agent yet?
- GitHub Copilot is free to start with a personal GitHub account. Install the Copilot extension in VS Code, or install the GitHub Copilot CLI and sign in from a terminal.
- Claude Code is a terminal-based coding agent from Anthropic. Its getting started guide covers installation.
- Use your organisation’s approved coding agent and data-handling environment for real HR data.
Once installed, open the agent in a folder that has R or Python available, then continue with the workflow below.
Workflow
- Export your data. Run a person query (or other query type) from the Viva Insights Analyst portal and download the CSV.
- Pick a prompt card. Browse the Prompt Library for the analysis task that matches your use case.
- Review the schema docs. Check Schema Documentation to understand the structure of your exported data: column definitions, expected granularity, and common pitfalls.
- Open your coding agent. Launch GitHub Copilot, Claude Code, or a similar tool in a workspace with R or Python available.
- Paste the prompt. Copy the prompt text from the card, point it at your data file, and let the agent generate the output.
- Review and iterate. Check the output against the documented failure modes and adaptation notes. Refine as needed.
Tips for working with coding agents
- Be specific about your data. Tell the agent the file name, column names, and date range. The more context you give, the better the output.
- Iterate in small steps. If the output is not right, ask the agent to fix one thing at a time rather than re-generating everything.
- Validate the output. Spot-check row counts, date ranges, and aggregation logic. Coding agents can make plausible-looking mistakes.
- Use the vivainsights packages. The R and Python packages handle common data validation and visualization tasks. Prompts that reference these functions tend to produce cleaner code.
See “Responsible use & data privacy” below before you work with real HR data.
Responsible use & data privacy
- Suppress small groups. Apply the stricter of your organisation's minimum group size and the selected workflow's privacy floor to every breakdown, segment and chart.
- Never expose individuals. Do not print raw UPNs or email addresses. Hash, truncate or report only aggregates. Person Query
PersonIdis already de-identified, but PurviewUserIdis not. - Report group patterns. Use these outputs to understand cohorts and trends. Do not evaluate, rank or monitor named employees.
- Keep data in approved environments. Follow your organisation's policies when choosing an agent and deciding which data it may access. Validate every agent output before sharing.
Quick links
Contributing
See the Contributing guide for how to add prompt cards and schema documentation.
This project uses the Microsoft Open Source Code of Conduct and requires a Contributor License Agreement for all contributions.